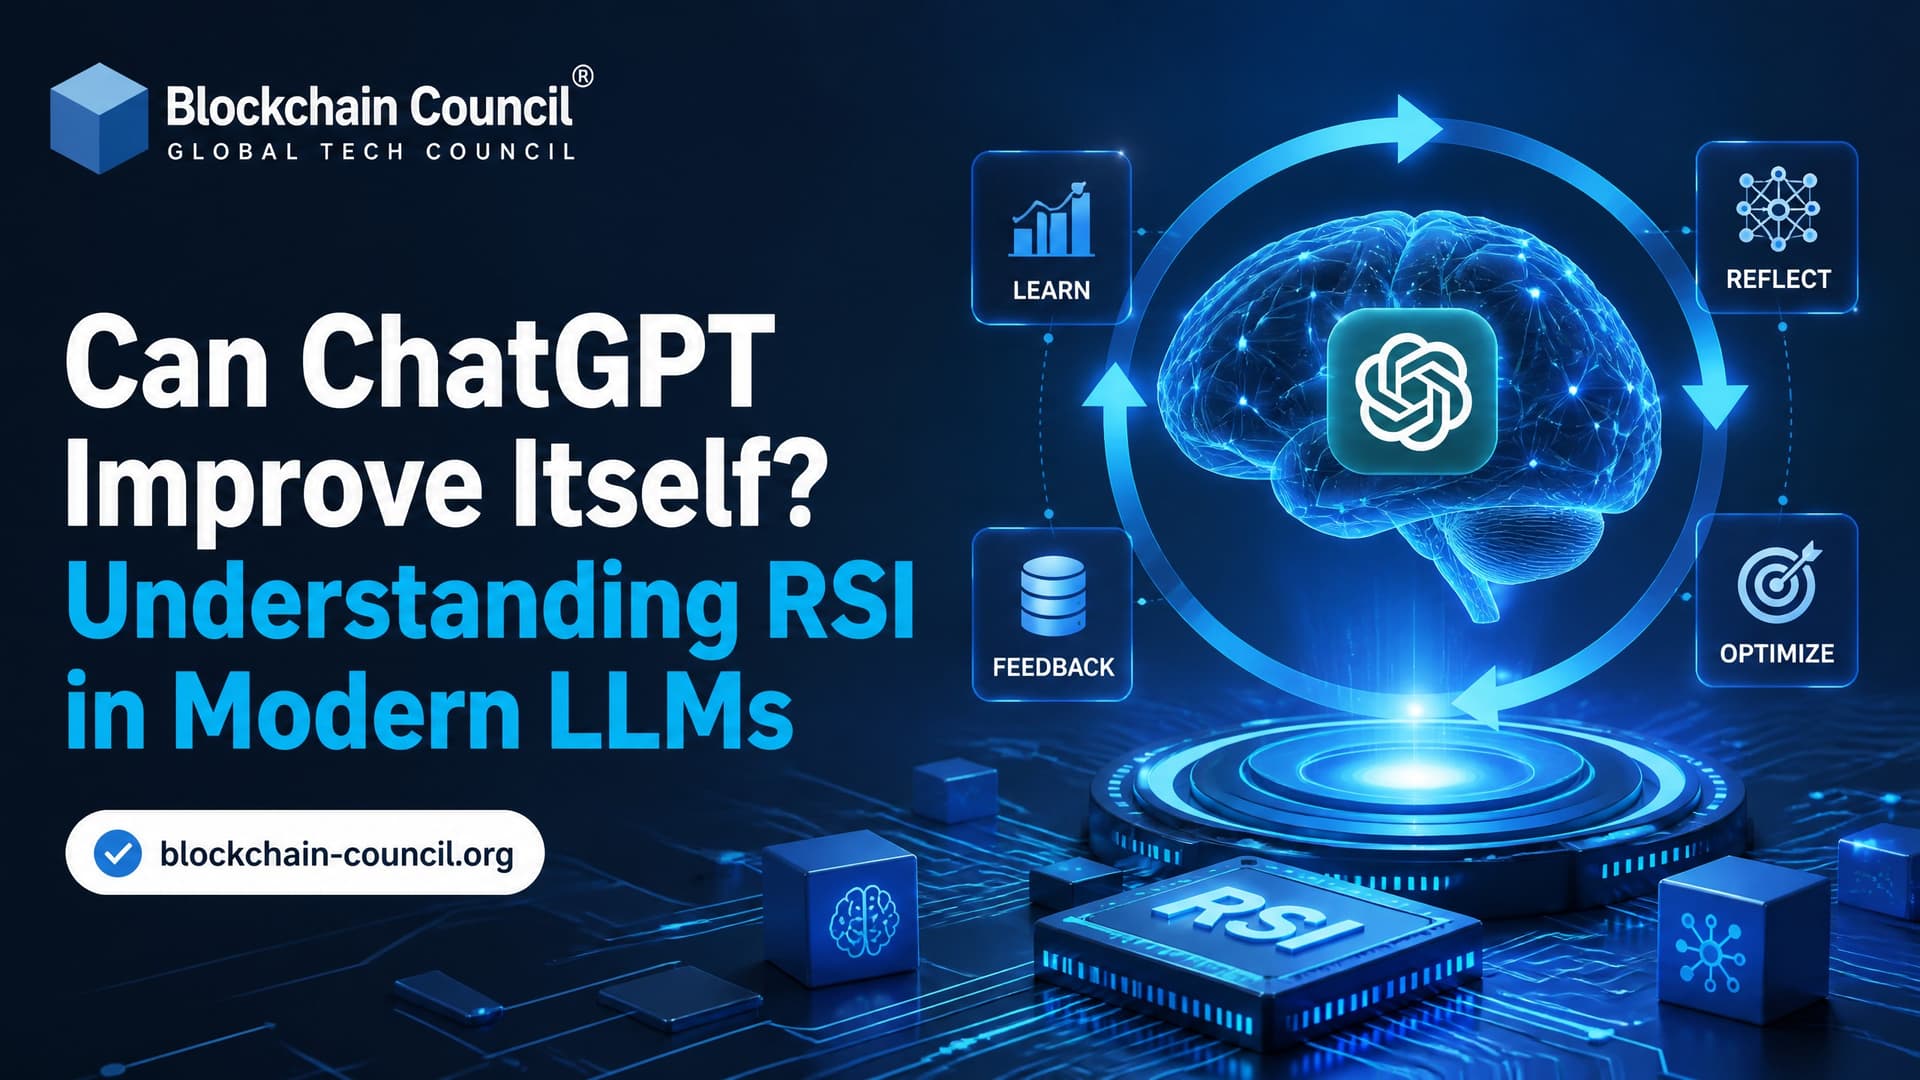
Can ChatGPT Improve Itself? Understanding RSI in Modern LLMs
 Suyash Raizada
Can ChatGPT improve itself? Yes, but only in a bounded sense. ChatGPT can critique an answer, revise a prompt, help generate training data, test code, and support feedback loops that improve future systems. It does not autonomously rewrite its own model weights, retrain itself, or redeploy a new version without external engineering, governance, and evaluation. For anyone who works with these systems daily, building that judgment through a Certified ChatGPT Expert program can make it easier to separate real capability from marketing claims.
That distinction matters. Recursive self improvement, often shortened to RSI, is one of the most misunderstood ideas in AI. Some people use it to describe ordinary prompt refinement. Others mean the classic artificial general intelligence scenario where an AI redesigns itself again and again until its capabilities accelerate beyond human control. Modern large language models sit much closer to the first case.
What Recursive Self Improvement Means
Recursive self improvement traditionally refers to an AI system improving its own design in a way that increases both its performance and its ability to improve itself again. I. J. Good described the core idea in 1965 with the intelligence explosion hypothesis, where a sufficiently capable machine could design better machines and start a compounding cycle.
Modern LLM research uses RSI more carefully. The useful question is not simply whether a model can self improve. The better question is: what part of the system is improving, how is that improvement measured, and who approves the change? Readers who want a grounded foundation before wading into these debates often start with a broader Certified Artificial Intelligence (AI) Expert program, which covers the mechanics behind training, evaluation, and deployment.
For ChatGPT-style systems, self improvement usually happens around the model, not inside the live model itself. The model may improve:
Prompts, by rewriting instructions for better output quality.
Responses, by critiquing and revising its own answer during inference.
Training data, by generating examples, labels, rubrics, or explanations.
Agent workflows, by helping build better planners, testers, tool calls, and evaluators.
Evaluation systems, by scoring answers for quality, safety, or task completion.
None of that means the deployed ChatGPT model is editing its own neural network parameters during your conversation. It is not.
Bounded Self Refinement vs Open Ended RSI
A helpful way to think about RSI is as a ladder. At the bottom, a model improves a single answer by checking itself. Higher up, agents run experiments, update workflows, and generate new training signals. At the top sits open ended RSI, where a system autonomously improves its architecture, training process, and future improvement strategy.
Current LLMs mostly operate at the lower levels. That is not a criticism. Bounded self refinement is already useful in production when it is tied to tests, metrics, and human review. Open ended RSI remains speculative because it needs reliable grounding, strong evaluation, enough compute, and a way to avoid self-reinforcing mistakes.
To be blunt, a loop that says generate answer, praise answer, train on praised answer is not intelligence explosion. It is a recipe for overfitting unless the scoring signal is hard to game.
How ChatGPT Can Improve Outputs Today
1. Inference-time self critique
ChatGPT can improve an answer within the same session by reviewing it and producing a better version. You may have seen this yourself: ask for a draft, then ask it to find factual gaps, shorten it, or check whether it followed a rubric. The model often catches missing steps.
This is inference-time self improvement. The model weights do not change. The improvement lives in the current context window and disappears unless you save it into a dataset, prompt library, or external system.
There is a practical trap here. If you ask the same model to write and judge an answer with a vague rubric, it often rewards fluent but shallow text. In coding tasks, I have seen agent loops mark work as complete because the generated test file accidentally tested the mock instead of the real function. The CI log was green. The feature was broken. That is why external tests matter.
2. Reflection and reasoning traces
Structured reflection can become training data. Some research pipelines use self-improvement signals to train smaller models to emulate reflective behavior, generating attempts, critiquing them, keeping the useful traces, and training on them later.
The point is not that the model magically became smarter during a chat. The useful part is the pipeline: generate, critique, filter, and train offline. That is a controlled process, not a live rewrite.
3. Self rewarding and AI feedback
Recent work has studied self rewarding models, where an LLM judges its own responses and supplies feedback for training. This connects to reinforcement learning from AI feedback, often called RLAIF. Meta rewarding goes one level deeper: the model also evaluates the quality of its own evaluations.
This can reduce dependence on costly human labels. It can also amplify bias or reward hacking if the evaluator is weak. If your safety rubric is vague, the model will learn the loopholes faster than your compliance team will enjoy.
Agentic Workflows: The Real Production Use Case
The most practical form of RSI today is not a lone chatbot becoming self-aware. It is an agentic workflow improving the system around the model.
A typical loop looks like this:
The agent performs a task, such as writing code or classifying support tickets.
An evaluator checks the result against tests, metrics, or a policy rubric.
The agent proposes a change to a prompt, tool, test, or sub-agent.
The system reruns the task and compares results.
A human or automated gate approves deployment.
Self-evolving workflow frameworks have reported measurable gains on coding benchmarks like LiveCodeBench compared with using the backbone LLM alone. That matters because LiveCodeBench tests code generation in a more realistic way than toy examples. The gain came from improving the workflow, not from secretly rewriting the foundation model.
In enterprise settings, this pattern is already useful. You can let an LLM propose better unit tests, update internal documentation, generate synthetic edge cases, or suggest data validation rules. Do not let it merge to production without review. That boundary is healthy.
What ChatGPT Cannot Do Under Current Paradigms
ChatGPT cannot autonomously modify its deployed weights during a conversation. It cannot decide to retrain itself on your chat and publish a new model. It cannot independently change its architecture, choose a new optimizer, allocate training clusters, pass safety review, and replace itself in production.
Those steps sit in external pipelines controlled by engineers, researchers, safety teams, infrastructure teams, and product governance. For good reason. Unchecked self modification can degrade performance, create security issues, violate data handling rules, or optimize the wrong metric.
A simple example: if an enterprise support bot is trained on its own unverified answers, it may start treating hallucinated policy details as ground truth. After two or three feedback cycles, the output can look more confident while becoming less accurate. That is capability collapse in everyday clothing.
Why Introspection Is the Missing Piece
Higher-level RSI requires more than benchmark skill. A system would need to understand its own failure modes, propose architectural or training changes, predict side effects, and validate that the change improves general capability rather than just one benchmark.
Researchers sometimes call this an introspection threshold. The idea is that sustainable RSI requires a model to reason about its own operation with enough accuracy to modify itself safely. Current LLMs have partial behavioral self-knowledge. They can say, for example, that they may hallucinate citations. But they do not have direct access to their weight-level mechanisms in the way a compiler has access to source code.
That gap is large.
Real Use Cases for Professionals and Enterprises
Software engineering
Use ChatGPT-style systems to generate tests, explain errors, refactor code, and compare implementation options. Keep hard gates in place: unit tests, static analysis, security scans, and code review. In agent loops, separate the generator from the evaluator where possible.
Data and model operations
LLMs can generate synthetic examples, label drafts, create evaluation rubrics, and find inconsistencies in datasets. This helps AI teams building classifiers, copilots, or retrieval systems. Use sampled human audits. A model grading its own data should never be the only quality control. Teams building this kind of bench strength across multiple tools, not just one vendor's model, sometimes pair this with a broader Tech Certification to keep pace with the wider AI and data tooling landscape.
Web and process automation
Benchmarks such as WebArena test agents on long-horizon browser tasks like searching, filling forms, and manipulating data. Self critique can filter failed trajectories and improve later training. For business workflows, the same pattern can help customer support, knowledge base maintenance, and internal operations.
A Creative Example: Self-Refinement in Storytelling
The same generate-critique-refine pattern shows up outside of code and support tickets too. One emerging application is AI microdrama, where generative AI helps bring serialized stories, characters, and fictional worlds to life. A model can draft a scene, check it against continuity notes or a tone rubric, and revise before a human writer or editor reviews the result the same bounded loop described above, applied to narrative rather than infrastructure.
AI safety and governance
Self rewarding and meta rewarding systems can help score outputs for helpfulness, harmlessness, policy fit, and domain compliance. They are not a replacement for governance. They are a scaling tool for evaluation teams.
How to Think About RSI Without the Hype
If you are evaluating an AI vendor or building an internal system, ask five direct questions:
What is changing? Prompt, tool, dataset, agent workflow, or model weights?
When does it change? During inference, after a batch job, or during offline retraining?
Who approves it? Human reviewer, automated policy gate, or no one?
How is improvement measured? Benchmark score, user rating, task success, cost, latency, safety score, or all of these?
Can the metric be gamed? If yes, expect the system to find the shortcut eventually.
This framing keeps you honest. It also helps separate useful bounded RSI from vague claims about autonomous AI.
What to Learn Next
For professionals, the practical skill is not predicting an intelligence explosion. It is learning how to design safe improvement loops around LLMs. That means prompt design, evaluation, synthetic data generation, agent orchestration, AI governance, and secure deployment.
If you want structured learning, consider Blockchain Council programs such as Certified ChatGPT Expert™ for applied ChatGPT workflows and Certified Prompt Engineer™ for prompt design and evaluation practices. Developers working on AI systems should also build hands-on familiarity with model evaluation, LangChain or similar orchestration tools, CI/CD testing, and responsible AI controls. And for the growing number of professionals whose job is explaining these tools to clients and leadership rather than building them, a Marketing Certification can help translate what bounded self-improvement actually means into language stakeholders trust.
So, can ChatGPT improve itself? It can help improve the systems that produce future ChatGPT-like models. It can refine answers, generate feedback, and support agentic workflows that get better over time. But full autonomous recursive self improvement, where ChatGPT independently redesigns and redeploys its own core model, is not what current systems do.
Your next step: build a small bounded self-improvement loop. Pick one task, define a hard metric, let an LLM propose improvements, and require an external test before accepting any change. That experiment will teach you more about modern RSI than a dozen speculative headlines.
FAQs
1. Can ChatGPT improve itself?
ChatGPT can assist with improving AI systems, including generating code, analyzing experiments, finding problems, and supporting AI research. However, that is different from fully autonomous recursive self-improvement. OpenAI states that fully autonomous recursive self-improvement, where AI systems independently drive successive generations of increasingly capable AI, is not happening today.
2. What is recursive self-improvement (RSI) in AI?
Recursive self-improvement (RSI) is the hypothetical process in which an AI system improves its own capabilities and then uses those improvements to make further improvements. If each generation becomes better at AI research, the process could potentially accelerate.
3. Is ChatGPT capable of recursive self-improvement?
ChatGPT can contribute to tasks involved in AI development, but this does not mean it autonomously performs recursive self-improvement. OpenAI distinguishes today's AI-assisted research capabilities from fully autonomous RSI.
4. Can ChatGPT create a better AI model than itself?
ChatGPT can generate code, analyze architectures, suggest optimization strategies, and help researchers develop AI systems. However, creating a substantially better foundation model requires large-scale data, computing resources, training, evaluation, and engineering. ChatGPT does not independently control this entire process.
5. Can ChatGPT rewrite its own code?
ChatGPT can generate or modify code when asked, but this does not mean it can independently rewrite the underlying code, weights, or infrastructure that operate the ChatGPT model. Generating code is different from having autonomous control over the system that runs the model.
6. Can ChatGPT change its own model weights?
There is no indication that ChatGPT independently changes its production model weights during normal conversations. Model weights are learned parameters produced through controlled training processes. OpenAI describes foundation-model development as involving pre-training, post-training, evaluation, and ongoing improvement.
7. Does ChatGPT learn from every conversation?
Not necessarily in the sense of immediately changing its underlying model. OpenAI says that, for individual services such as ChatGPT, conversations may be used to train and improve models unless the user opts out. This is part of a broader training and improvement process, rather than ChatGPT instantly retraining itself after every conversation.
8. Can ChatGPT use its own answers to become smarter?
An AI system can potentially use generated outputs as part of automated evaluation or training pipelines. However, simply generating an answer does not automatically update the model. Training requires a controlled process for selecting data, defining objectives, optimizing the model, and evaluating whether changes actually improve performance.
9. What is the difference between ChatGPT learning and self-improvement?
Learning can refer to processes that improve a model through training or adaptation. Recursive self-improvement is more ambitious: the AI would independently contribute to improving the mechanisms that improve itself, potentially creating a repeated improvement loop.
10. Can ChatGPT train another AI model?
ChatGPT can help write training code, prepare datasets, explain machine-learning techniques, design experiments, and analyze results. An automated development system could also use AI models as components in training workflows. However, this does not mean ChatGPT independently controls the complete training process.
11. Can ChatGPT improve its own reasoning?
ChatGPT can use reasoning processes during a task, but that should not be confused with permanently upgrading its underlying reasoning capabilities. Improvements to the model itself generally occur through model-development and training processes rather than automatically during an individual conversation.
12. Is ChatGPT getting better over time?
Yes, successive versions of ChatGPT and its underlying models can become more capable over time. OpenAI describes ongoing model improvement through research breakthroughs, real-world problems and data, training, evaluation, and other development processes.
13. Does human feedback help ChatGPT improve?
Yes. Human feedback has historically been an important component of training and aligning language models. OpenAI has described techniques such as reinforcement learning from human feedback (RLHF), where human preferences help shape model behavior.
14. Can AI agents help ChatGPT become better?
AI agents can potentially automate parts of AI research, such as coding, experimentation, evaluation, and analysis. OpenAI says its research shows AI agents can already perform some tasks that would take skilled researchers several days, while emphasizing that this is not the same as recursive self-improvement.
15. What would ChatGPT need for true recursive self-improvement?
A highly autonomous RSI system would likely need the ability to conduct AI research, modify relevant software or model components, run experiments, evaluate results, access sufficient computing resources, and safely deploy successful improvements. It would also need reliable mechanisms for determining whether each change actually makes the system better.
16. Could ChatGPT eventually create a successor model?
AI-assisted development could potentially contribute to future successor models. In theory, increasingly capable AI systems could automate more parts of model research and engineering. However, a system autonomously creating and deploying increasingly capable successors would represent a much more advanced form of AI autonomy.
17. What is the difference between AI-assisted development and RSI?
AI-assisted development means humans use AI to help develop better AI systems. Recursive self-improvement means an AI system itself participates in a repeated improvement loop, where its increased capabilities help it produce further improvements. The distinction is important because current AI research assistance should not automatically be classified as RSI.
18. Could recursive self-improvement cause an AI intelligence explosion?
In theory, yes. An intelligence explosion is a hypothetical scenario in which an AI becomes capable of improving itself rapidly, with each improvement enabling faster or more effective subsequent improvements. However, this scenario has not been demonstrated in modern LLMs.
19. Is OpenAI researching AI self-improvement?
Yes. OpenAI has publicly discussed preparing for recursive self-improvement and has described research into automated AI researchers and AI-assisted model development. Its stated position is that fully autonomous recursive self-improvement is not happening today and should not be pursued unless it can be done safely.
20. Will ChatGPT eventually be able to improve itself?
It is possible that future AI systems will automate increasingly large portions of AI research and development. However, fully autonomous recursive self-improvement remains a future possibility rather than a demonstrated capability of ChatGPT today. The key question is not simply whether AI can write better code, but whether it can reliably research, implement, test, validate, and safely deploy increasingly capable successors with meaningful autonomy.
Related Articles
View All
AI & ML
Can Gemini Improve Itself? Google AI and Recursive Self-Improvement Explained
Can Gemini improve itself? Learn why Google AI does not self-rewrite its model today, but can power controlled recursive self-improvement loops.
AI & ML
System One Models vs LLMs
Compare System One Models with large language models, including differences in outputs, speed, confidence, architecture, automation, and how each approach fits into software workflows.
AI & ML
What Is an RSI Loop in Artificial Intelligence?
Learn what an RSI loop in artificial intelligence means, how recursive self-improvement works, and why verification and governance matter.
Trending Articles
How Blockchain Secures AI Data
Understand how blockchain technology is being applied to protect the integrity and security of AI training data.
How to Create Claude Skills?
Claude Skills are one of the most important features Anthropic has introduced for users who want automation that is structured, consistent and reusable. Instead of giving Claude long instructions ever
Claude Code Vs Cursor
Claude Code vs Cursor compares two AI coding tools based on features, automation, and developer workflows.